Cognitive Architecture and AGI: What a Global Workspace Model Can Actually Demonstrate
Key takeaways
- An architecture is an organization of processes, not a guarantee of general intelligence.
- Global-workspace proposals concern access and coordination across systems.
- A human theory test does not certify an AI system as conscious.
- A model needs comparisons and failure tests beyond an appealing brain analogy.
A system may remember a task, select a relevant detail and choose a next action. Describing these functions with familiar psychological words can help explain its design. It can also make a software demonstration sound more human than the evidence warrants.
Cognitive architecture provides a way to make the organization explicit. Instead of asking whether a system seems generally smart, ask how information moves between its parts and what the resulting design can do. That question is useful for engineering and science without assuming that the program possesses a human mind.
What counts as a cognitive architecture?
An architecture describes relationships among processes and representations. It might specify where information is stored, how competing inputs receive attention, how a goal influences a choice and how an action changes the next input. A diagram is a starting point, not the complete implementation.
The same broad functional labels can conceal different mechanisms. Memory could mean a temporary state, a searchable record or learned parameters. Attention could refer to a selection rule or a mathematical operation in a model. Naming the component does not establish equivalence with its biological counterpart.
For a practical reading exercise, replace each familiar label with its actual operation. What gets written? What gets read? Which process can change the value? What triggers an update? The resulting description is more testable than a collection of human-sounding names.
The global-workspace idea
In global-workspace approaches, many specialized processes operate while selected information becomes available more broadly. The central idea is coordination and access. A workspace is not necessarily a literal single place in a machine, and the metaphor should not become an anatomical claim.
Baars and Franklin's 2007 architectural paper describes a hybrid model connecting global-workspace ideas with distributed processes and the IDA/LIDA research program. It is a proposal for relating functions and mechanisms, not a report that a system passed a universal test for consciousness or intelligence.
Its value as a source is the explicit organization it proposes. A reader can ask which predictions follow from that organization and how an implementation would differ from alternatives. Those questions keep the theory open to investigation rather than treating the word workspace as an explanation by itself.
A library analogy, with limits
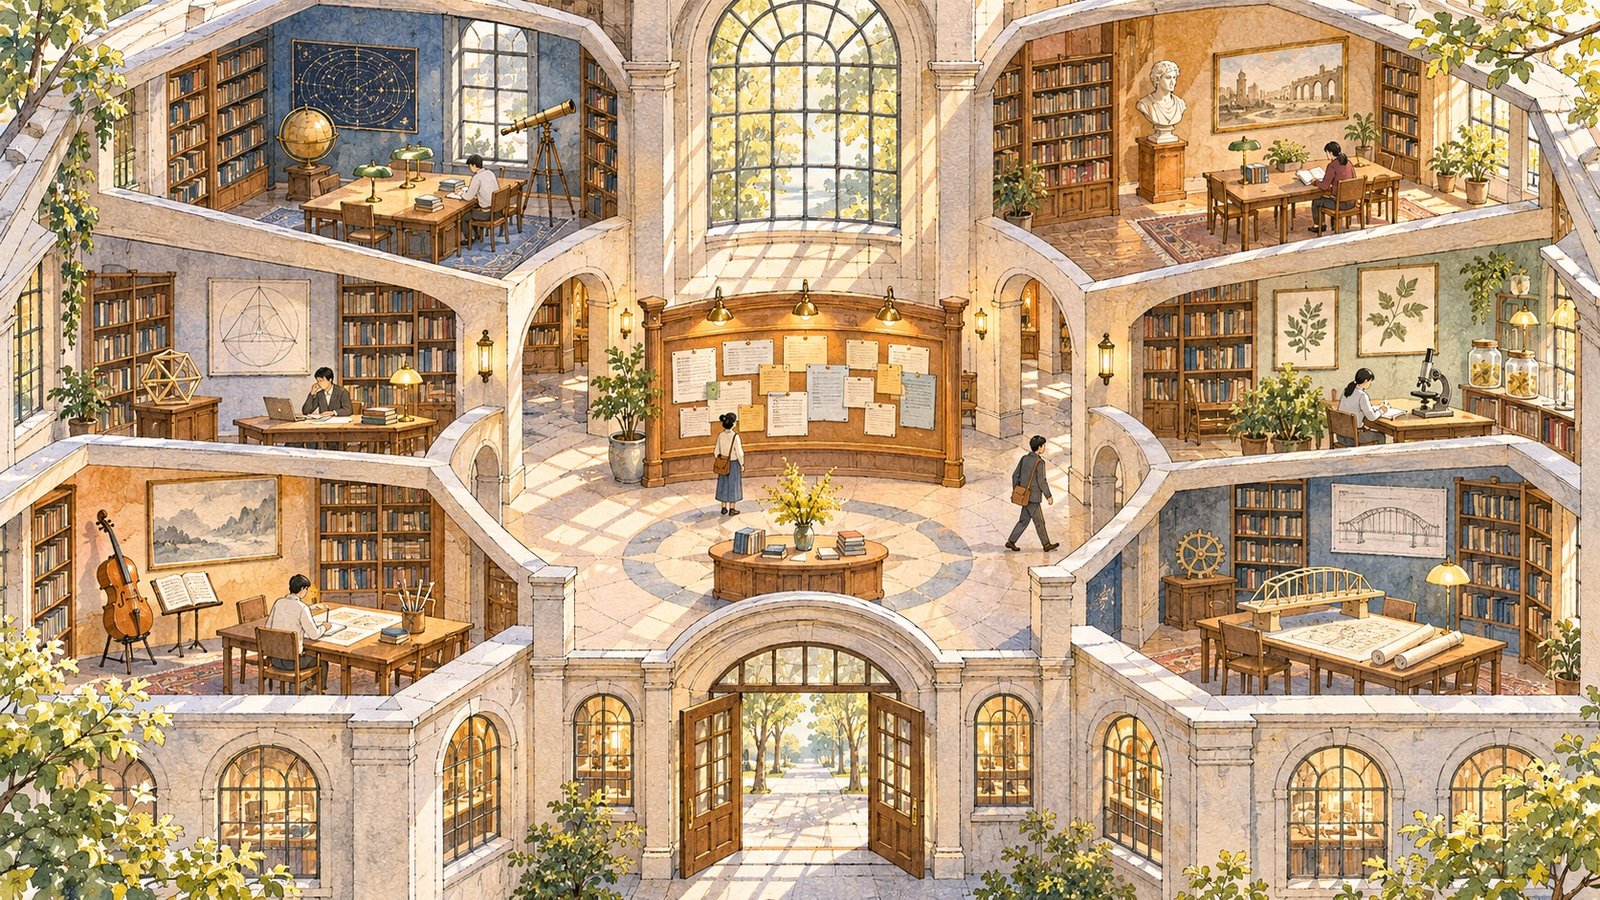
Imagine an original conceptual library with several workrooms and a shared notice board. Each room handles a specialized task. Some information is placed on the board so other rooms can use it without duplicating the original work.
This analogy makes selective sharing understandable. It does not establish what any room experiences or prove that a shared board is the only possible organization. Nor should the building be treated as a literal diagram of cortical anatomy.
The useful next questions are operational. Who chooses what reaches the board? How long does it remain available? Can irrelevant messages crowd out useful ones? What happens when two tasks compete? A proposed architecture becomes scientifically interesting when it supplies answers that can be tested.
What a human theory test can contribute
The 2025 Cogitate collaboration tested contrasting predictions from global neuronal workspace theory and integrated information theory in 256 human participants. Participants viewed clearly visible stimuli, with measurements involving fMRI, MEG and intracranial EEG across the research program.
The report found support for some predictions while challenging important claims from both theories. This was not a declaration that consciousness had been solved or a test of whether a language model has experiences. The participants, stimuli and measurements define the study’s scope.
For software claims, the lesson is methodological: specify predictions before observing results and identify findings that would count against the explanation. A human-neuroscience result can motivate architectural hypotheses without validating every machine that borrows the same vocabulary.
General intelligence is a different target
Before claiming progress toward artificial general intelligence, define what generalization means in the project. Does the system solve new tasks, adapt to changed rules or apply a skill in a different setting? Performance on one familiar benchmark does not answer all of those questions.
An original hypothetical agent might succeed at sorting messages in a fixed workflow. If a new rule changes which messages matter, the agent could fail despite excellent performance on its original task. That failure would reveal a limit on the tested generalization, not necessarily a defect in every component.
Likewise, a workspace component can improve a particular task without making the complete system generally intelligent. The contribution should be reported precisely: this mechanism changed this behavior under these conditions. A broader label requires broader evidence.
Working memory is not simply more storage
A temporary store can help a program maintain information relevant to a task. Whether that store functions like a proposed working-memory mechanism depends on how it is selected, updated and used. Capacity alone does not describe those operations.
For a hypothetical scheduling agent, retaining every prior message may be less useful than keeping the current constraints accessible. The key design problem is maintaining the right information and revising it when the task changes, rather than merely increasing the number of saved tokens.
When a demonstration uses a memory label, ask which behavior requires it. Then compare with a version that lacks the proposed feature or uses a simpler alternative. That comparison can test a functional claim without assuming that the software reproduces human working memory in full.
Architecture, algorithm and hardware are different
An architecture organizes components. An algorithm specifies a procedure. Hardware supplies the physical computation. These levels interact, but a result at one level does not automatically validate the others.
Our neuromorphic hardware guide focuses on physical implementation and benchmarking. A spiking chip could run a limited task, and a global-workspace-inspired program could run on conventional hardware. Neither label alone establishes general intelligence or consciousness.
Similarly, our neural-network and synapse comparison explains why computational success does not identify a biological learning rule. The same restraint applies when a high-level architecture is presented as a completed explanation of the mind.
Tests that would make a demonstration informative
| Test | Useful question | What a positive result would still leave open |
|---|---|---|
| Component removal | Does the proposed mechanism affect behavior? | Whether a simpler substitute could do the same |
| Changed rules | Can the system adapt beyond its original task? | Generality across unrelated tasks |
| Distractor input | Does selection protect relevant information? | The full mechanism of human attention |
| Conflicting goals | How are priorities resolved? | Conscious deliberation or subjective experience |
These are evaluation questions, not a certification checklist. A task needs an appropriate comparison and a meaningful outcome. The aim is to expose the design’s contribution and limits rather than accumulate impressive-sounding tests.
Metacognition needs an operational definition
A system may produce a confidence statement, request help or check an earlier output. Those behaviors can be useful, but a sentence such as I am uncertain does not establish that its confidence tracks actual reliability.
Ask how the statement changes with errors, unfamiliar inputs and misleading information. If confidence remains high when performance falls, the behavior may not serve the intended monitoring function. A polished explanation should not replace an evaluation of the relationship between the report and the outcome.
This is particularly relevant when a product claims self-awareness or reflection. The practical question may be whether the tool detects a failure and routes the task appropriately. That useful capability can be tested without resolving every philosophical question about awareness.
Before buying a brain-inspired AI promise
Identify the job you need done and the evidence that the architecture improves it. Ask for a comparison, the conditions under which the system fails and the cost of supporting components. A neuroscience reference does not establish that a product is suitable for a particular workflow.
For a course, look for implementations, explicit assumptions and exercises that compare alternatives. A module that draws a workspace diagram may explain a theory without teaching how to evaluate an agent. Neither outcome is inherently wrong; they serve different learning goals.
No service is ranked or personally tested here. The decision should depend on demonstrated task value, access, privacy and cost. Avoid paying extra for a claim of human-like cognition when the actual benefit is a narrower and more ordinary software function.
Frequently asked questions
Does a global workspace make an AI conscious?
Implementing a workspace does not establish subjective experience. It supplies an architecture whose functional claims can be tested. The interpretation of consciousness requires additional theoretical and evidential commitments.
Did the 2025 human study settle which theory is correct?
No. It reported findings that aligned with some predictions and challenged others. Its design and visible-stimulus conditions matter when interpreting what was tested and what remained open.
Is a brain-inspired system necessarily more general?
No. Generalization must be evaluated through tasks and changed conditions. Inspiration can guide a design without proving that it transfers broadly or matches human abilities.